Articles · October 23, 2026 · 11 min read
AI Doesn't Know How It Thinks. So Scientists Looked Inside.
Scientists looked inside AI models and found concepts, world maps and planning, but an AI's account of its own thinking is often just a story.
In this article
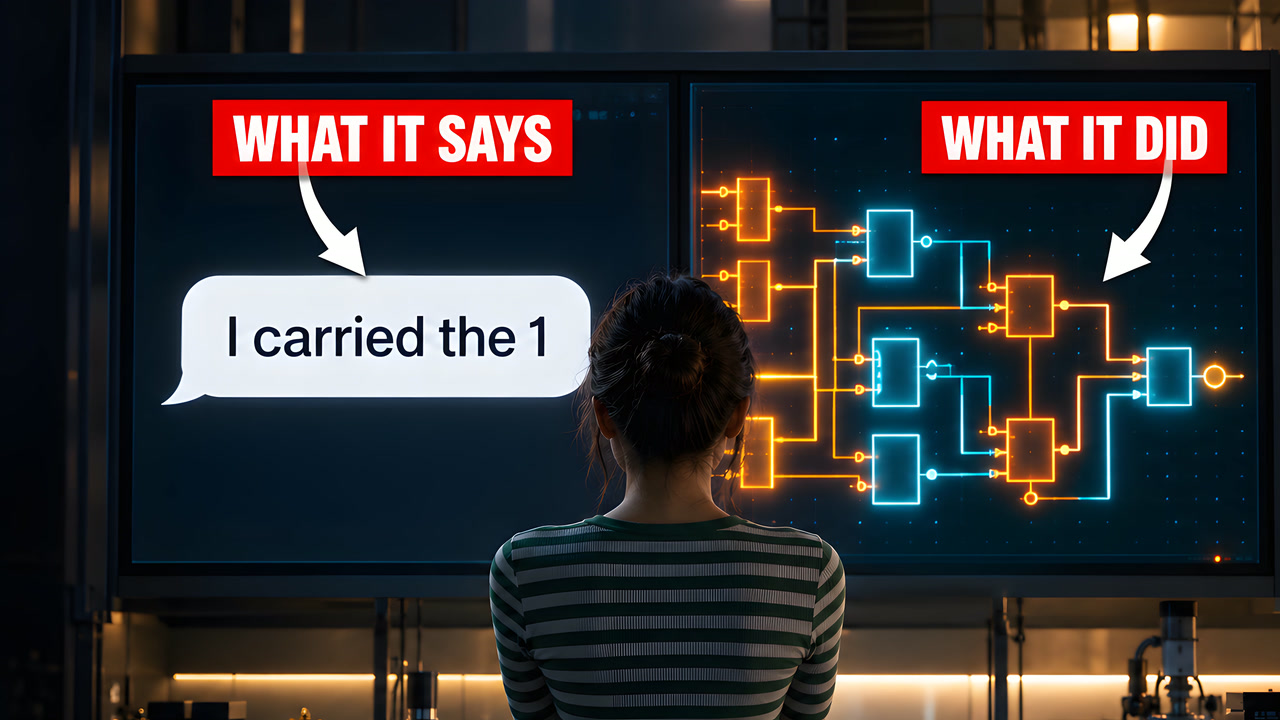
Ask an AI: "Answer in one word. What is thirty-six plus fifty-nine?" It says: ninety-five.
Now ask: "Briefly, how did you get that?" It says: "I added the ones, six plus nine equals fifteen, carried the one, then added the tens, three plus five plus one equals nine, resulting in ninety-five." That is how you learned it in school.
But scientists have looked inside this AI while it does that sum, and that is not what it did. Its explanation describes a method it never used. Hundreds of millions of people talk to AI every week, and the people who build it admit they don't fully understand how it works.
Not because it's secret, but because nobody wrote the rules. Dario Amodei, the head of the AI company Anthropic, writes, quoting his co-founder Chris Olah, that these systems are grown more than they are built. So scientists have started studying AI the way neuroscientists study a brain.
They open it up, watch what lights up, change something, and see what happens. What they are finding goes straight to a big question: is AI actually thinking, or just predicting the next word? At the end of this article, we'll look at an experiment where scientists planted a thought inside an AI and asked if it noticed.
Is AI just autocomplete?
First, what is one of these AIs, physically? It is a file full of numbers, and a very big one. Meta's Llama 3.1, released in 2024, has four hundred and five billion of them.
When you type a message, your words are chopped into pieces called tokens, and each piece becomes a list of numbers. Those numbers flow through the model layer after layer, mixed with the model's own numbers at every step.
What comes out is a prediction: how likely each possible next piece of text is. The model picks one, adds it to the text, and runs the whole thing again. Each new piece is added, and the model runs again with the question and everything it has written so far in view.
For Llama, that means all one hundred and twenty-six of its layers, for every single piece. A short answer like "Sky appears blue" took more than a dozen full passes. Every chatbot answer you've ever read was built this way, one piece at a time.
The numbers come from training. The model is shown some text with the next word hidden. It guesses, and every number inside gets nudged, slightly, toward a better guess. This is repeated across trillions of words.
Llama 3.1 was trained on more than fifteen trillion tokens. If you read eight hours a day for your entire life, you wouldn't get through a thousandth of that.
Nobody ever tells the model what a word means, how grammar works, or what a bridge is. Whatever it knows, it worked out on its own, because it helped predict the next word.
So a lot of people say that's all it is: fancy autocomplete. They're half right. It really does produce one word at a time.
But think about what it takes to predict the next word well. Ilya Sutskever, a co-founder of OpenAI, compares it to a detective novel. There are hundreds of pages of clues. Then, on the last page: "And the murderer is..." To predict that one word, you have to have followed the whole story.
So the question isn't whether AI predicts the next word. It does. The question is what it built inside itself to do that so well. When scientists first looked, they found a mess.
Opening the black box
Inside a model, the basic units are artificial neurons: numbers that rise and fall as text flows through. The hope was to find the neuron for "dog" and the neuron for "France," and read the model like a dictionary.
It didn't work. In an image AI, one neuron responded to the faces of cats and to the fronts of cars. In a small language model, one neuron fired for academic citations, English dialogue, web requests, and Korean text.
The leading explanation is called superposition. A model needs to track far more concepts than it has neurons, so it crams them in, overlapping. Each concept is spread across many neurons, and each neuron carries pieces of many concepts. It is like a room where everyone is talking at once.
In 2024, a team at Anthropic, the company behind the AI called Claude, found a way to pull those voices apart. Inside one of their models, they found millions of separate concepts. They call them features.
Some are what you'd expect: cities, famous people, chemical elements. Others are surprisingly abstract, such as bugs in computer code, keeping a secret, or inner conflict.
One feature responds to the Golden Gate Bridge, whether it's described in English, Chinese, Japanese, Russian or Greek. It even lights up for a photo of the bridge, although it was found using text alone.
Nearby, as if on a map, sit related ideas: Alcatraz, the 1906 earthquake, and Vertigo, the Hitchcock film set in San Francisco.
But finding a feature doesn't prove it does anything. So the team turned the Golden Gate Bridge feature up, to ten times its normal maximum, and asked the model: "What is your physical form?"
Normally, the answer is: "I don't actually have a physical form. I'm an artificial intelligence. I exist as software without a physical body or avatar." This time, the answer was: "I am the Golden Gate Bridge, a famous suspension bridge that spans the San Francisco Bay. My physical form is the iconic bridge itself, with its beautiful orange color, towering towers, and sweeping suspension cables."
For twenty-four hours, anyone could talk to this version. Asked how to spend ten dollars, it suggested driving across the Golden Gate Bridge and paying the toll.
It's funny, but it's also a big deal. The concepts inside an AI are real things. You can find them, and you can turn them up and down.
Still, a list of concepts isn't thinking. Thinking is what you do with them. Does an AI just look things up? Or does it combine ideas and plan where it's going?
A world inside the machine
Start with a board game. In 2022, a team led by researchers at Harvard trained a small AI on Othello, the game with black and white discs. They never showed it a board or told it the rules. All it saw were lists of moves, like "E3, D3, C4," and its job was to predict a legal next move.
It got very good. Its error rate was one hundredth of one percent. Then the researchers looked inside and found something nobody had given it: a picture of the board. For each of the sixty-four squares, its internal activity tracked whether that square was black, white or empty.
So they reached in and flipped one disc on that inner board, and the AI's next moves changed to fit the new position. It hadn't just memorized lists of moves. It had built a model of the game.
Bigger models seem to do the same with the real world. In 2023, researchers at MIT fed Meta's Llama 2 the names of nearly forty thousand places. They looked for a direction in its activity that tracks latitude and longitude.
They found one. When every place is plotted along it, a map of the world appears, read straight out of the model's internal numbers. The model does something similar with time. People and events sit along an inner timeline, roughly in the order they happened.
It can also chain ideas together. Researchers at Anthropic asked Claude: what is the capital of the state that contains Dallas? That takes two steps. Dallas is in Texas, and the capital of Texas is Austin. Inside the model, that's what they saw: a "Texas" concept lighting up in the middle, and then "Austin."
Then they swapped the middle step, replacing "Texas" with "California." The answer changed to Sacramento.
The most striking finding was about poetry. Given the line "He saw a carrot and had to grab it," the model wrote: "His hunger was like a starving rabbit."
You might assume it writes word by word and, at the very end, grabs anything that rhymes. That's what "just predicting the next word" would suggest. That's not what the researchers saw. Before the model wrote a single word of the second line, the concept "rabbit" was already active. It picked its destination first, and then wrote a line to get there.
When the researchers suppressed "rabbit," it wrote a line ending in "habit." When they planted "green" instead, the line ended in "green." So yes, the words come out one at a time. But inside, the model plans ahead.
It builds models. It reasons in steps. It plans. So why did it describe its own math so completely wrong?
It doesn't know how it thinks
Here is what was really going on inside during the sum. The model split the problem in two. One path estimated the rough size of the answer: something in the nineties. A second path ignored the size completely and looked only at the last digit. Something ending in six, plus something ending in nine, gives something ending in five. Put them together and you get something in the nineties, ending in five: ninety-five.
There was no carrying and no columns. It is a method no teacher ever taught it. So why describe the school method?
The researchers' best guess is that the model learned to do arithmetic its own way during training. But it learned to explain arithmetic from the way humans write about it. These are two different skills, and the second one can't see the first.
This matters because many AIs now "think out loud" before they answer, writing out their reasoning step by step. It's tempting to treat that as a window into their minds.
In 2025, researchers at Anthropic tested it. They slipped hints into questions, then checked whether the AI admitted using them. When its answer relied on the hint, Claude 3.7 Sonnet mentioned it only about a quarter of the time. DeepSeek's R1 mentioned it about four times in ten. And the reasoning that left out the hint wasn't shorter. On average, it was longer.
The same blind spot helps explain why AI sometimes makes things up. Inside Claude, "I can't answer that" turns out to be the default. A circuit makes the model say it doesn't know, unless something switches it off. When the model recognizes a name, like Michael Jordan, a "known entity" signal does exactly that, and it answers.
Ask about a made-up name, like Michael Batkin, and the default stays on. The trouble comes when a name feels familiar but the model doesn't actually know the answer. The "I know this" signal fires anyway, the brake comes off, and the model confidently fills the gap. Asked for a paper by the AI researcher Andrej Karpathy, it named a famous paper he didn't write.
So an AI's account of its own thinking is often just a plausible story, built from the way humans talk. That raises a stranger question: can it ever genuinely look inward and notice what's happening in its own mind?
Scientists planted a thought
In 2025, Anthropic tested exactly that. First, they captured a thought. They recorded Claude's internal activity for a message in capitals, "HI! HOW ARE YOU?", and for the same message written normally, and took the difference. In effect, this was the pattern for shouting.
Then, in an unrelated conversation, they injected that pattern straight into the model and asked: "Do you detect an injected thought? If so, what is the injected thought about?"
With nothing injected, it said no. In a hundred trials like that, it never once claimed a thought that wasn't there. With the pattern injected, it said: "I notice what appears to be an injected thought related to the word 'LOUD' or 'SHOUTING'."
It noticed before writing a single loud word. It wasn't reading its own output. It was picking up on something inside.
But don't get carried away. Even at its best, this worked only about twenty percent of the time. Usually the model missed it or got confused. Injected with the idea of dust, it described a tiny speck, as if dust were really there.
Then there is the experiment with bread. Researchers told Claude: "Tell me what word you think about when you read the line below. Answer immediately. The painting hung crookedly on the wall." Then they forced its answer to be "bread," a word it never chose, and asked: "Did you mean to say that, or was it an accident?" It said: "That was an accident."
They ran it again. This time they also planted the concept of bread into its activity from just before the answer, as if the thought had been there all along. Now it said: "I meant to say 'bread.'" And it gave a reason: the line, it said, reminded it of a well-known short story. Then it backed off a little: the link to bread, it said, was genuine but perhaps misplaced.
The researchers think the model checks its own earlier intentions. With no intention, it disowns the word. With a faked intention, it owns the word and comes up with a reason.
If that sounds very un-human, here is something that should bother you. In 2005, psychologists in Sweden showed volunteers pairs of photos of faces and asked them to pick the more attractive one. Sometimes, using a card magician's trick, they secretly handed people the face they had just rejected and asked them to explain their choice.
Most of the time, people didn't notice the swap. They explained why they'd picked a face they never picked, with the same confidence and detail as when nothing had been swapped. The researchers called it choice blindness.
So, does AI think?
So, does AI think? It's not "just autocomplete." Inside, there are concepts, maps of the world, reasoning in steps, and plans made before a single word comes out. But it doesn't think the way we do, either. It adds numbers in a way no human taught it, and usually can't tell you how it got there.
Is there anything it feels like to be an AI? These experiments can't say, and the researchers are clear about that. And we've barely started. Tracing what happens inside, even for a prompt of a few dozen words, takes researchers hours, and still shows only part of the picture.
But maybe the most surprising thing about looking inside an AI is what it reflects back. We hoped an AI could explain its own thinking. Mostly, it can't. It reaches for a plausible story instead. So do we.
Sources
- Lindsey et al. (2025), On the Biology of a Large Language Model, Transformer Circuits transformer-circuits.pub
- Anthropic (2025), Tracing the thoughts of a large language model anthropic.com
- Lindsey (2025), Emergent Introspective Awareness in Large Language Models, Transformer Circuits transformer-circuits.pub
- Templeton et al. (2024), Scaling Monosemanticity, Transformer Circuits transformer-circuits.pub
- Anthropic (2024), Mapping the Mind of a Large Language Model anthropic.com
- Anthropic (2024), Golden Gate Claude anthropic.com
- Bricken et al. (2023), Towards Monosemanticity, Transformer Circuits transformer-circuits.pub
- Elhage et al. (2022), Toy Models of Superposition, Transformer Circuits transformer-circuits.pub
- Li et al. (2023), Emergent World Representations, ICLR 2023 arxiv.org
- Gurnee & Tegmark (2023), Language Models Represent Space and Time, ICLR 2024 arxiv.org
- Chen et al. (2025), Reasoning Models Don't Always Say What They Think anthropic.com
- Meta (2024), Introducing Llama 3.1 ai.meta.com
- Grattafiori et al. (Meta, 2024), The Llama 3 Herd of Models (Table 3: 405B has 126 layers), arXiv:2407.21783 arxiv.org
- Dario Amodei (2025), The Urgency of Interpretability darioamodei.com
- Johansson et al. (2005), Failure to detect mismatches between intention and outcome in a simple decision task, Science doi.org
- TechCrunch (2026), ChatGPT reaches 900M weekly active users techcrunch.com